Event-Driven Commerce Migration
Peak-hour monolith failures + inflated EC2 → 5M+ orders/mo, P99 <200ms, ~30% infra reduction.
- Role
- Senior Software Engineer
- Context
- Retail / E-Commerce
- Duration
- 8 months
- Team
- 4 engineers + 1 architect (me)
Why they called
A PHP monolith on EC2 was failing under promotion traffic. Peak capacity was around 500 requests a second with P99 latency near 2.8 seconds, failures cascaded under load, deploys were weekly and manual, and the instances had been oversized to compensate. Every promotion was a gamble on whether checkout would stay up.
Tech stack
- Node.js
- Go
- Kafka
- ECS/EKS
- Kubernetes
- Redis
- MySQL
- Terraform
- GitHub Actions


Business problem and production context.
Business problem
Legacy PHP monolith on EC2 couldn't handle peak-hour traffic spikes during promotions. Deployments were risky, costs were inflated from overprovisioned instances, and the system suffered from cascading failures under load.
Architecture decision
Led migration using the Strangler Fig pattern, incrementally routing traffic from the monolith to event-driven microservices built with Node.js, Go, and Kafka on ECS/EKS. Implemented blue-green deployments and auto-scaling on Kubernetes for zero-downtime releases.
Before and after.
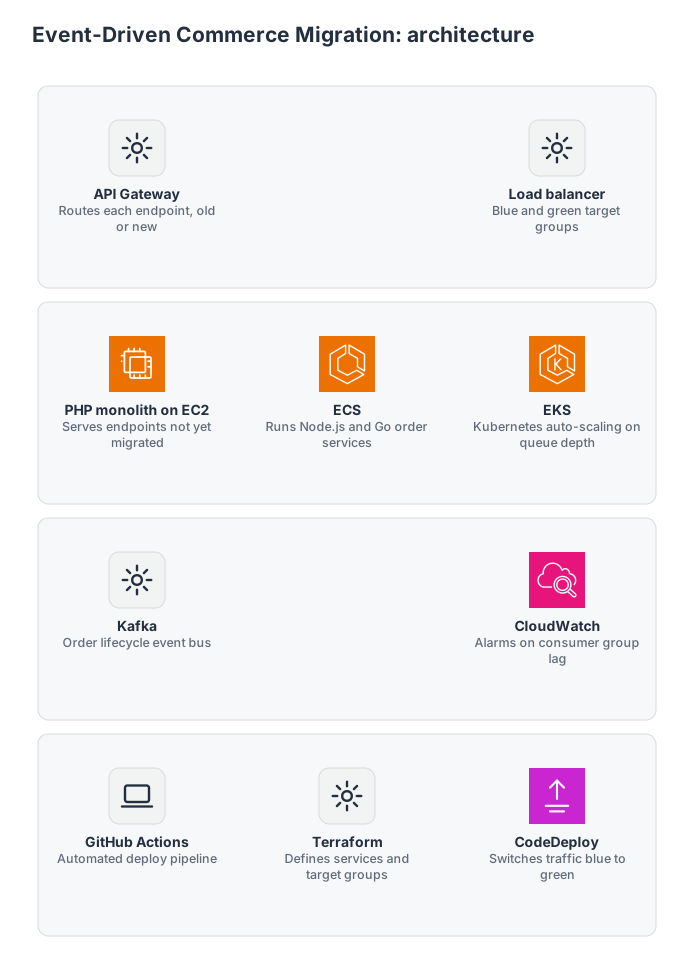
Order traffic moved off a PHP monolith one endpoint at a time, with orders flowing through Kafka events.
The routing, order services, event bus and release path. Networking, the data stores and the monolith's internals are not shown.
Main components only; supporting services are left out.
Routing
API Gateway
Routes each endpoint, old or new
Load balancer
Blue and green target groups
Services

PHP monolith on EC2
Serves endpoints not yet migrated

ECS
Runs Node.js and Go order services

EKS
Kubernetes auto-scaling on queue depth
Events
Kafka
Order lifecycle event bus

CloudWatch
Alarms on consumer group lag
Release and operations
GitHub Actions
Automated deploy pipeline
Terraform
Defines services and target groups

CodeDeploy
Switches traffic blue to green
How it works, step by step
- 1The API Gateway sends each migrated endpoint to the new services and leaves every other endpoint on the PHP monolith.
- 2Node.js and Go services handle the request and publish order lifecycle events (placed, confirmed, dispatched, delivered) to Kafka instead of calling each other directly.
- 3Downstream services consume those events, and Kubernetes scales them on order queue depth during promotions.
- 4CloudWatch alarms on Kafka consumer group lag flag delayed order confirmations.
- 5Each release goes out blue-green through CodeDeploy, so a bad release rolls back by switching traffic to the previous target group.
Guardrails
- Strangler fig routing, endpoint by endpoint, starting with order search before checkout
- Old and new systems ran in parallel, comparing response times and error rates before cutover
- Blue-green deployments for fast rollback
- Auto-scaling tied to order queue depth
- CloudWatch alarms on Kafka consumer group lag
Considered and not used
- Lambda as the main compute: Containers chosen for long-running order processing workflows and predictable latency.
- SQS: Kafka chosen for high-throughput event streaming with replay.
- Canary deployments: Blue-green chosen for simpler rollback during critical commerce operations.
My part of the work, separate from the team's.
The team behind the engagement is in the facts row above. These are the parts I was responsible for, and the artifacts that show the work.
Owned scope
- Migration path from fragile monolith endpoints toward independently deployable order services
- Traffic, latency, rollback, and event-flow decisions for peak commerce load
- Operational shape for blue-green releases and queue/consumer monitoring
Evidence artifacts
What would fail first?
Every project has constraints. The useful work is naming them early enough that rollback, cost, and ownership are designed before an incident.
Peak traffic
Promotion traffic created sharp spikes where synchronous paths and overprovisioned compute both hurt.
Revenue path
Checkout and order flows had to migrate without creating customer-visible downtime.
Mixed stack
The migration needed to coexist with a legacy PHP monolith during staged cutover.
Trade-offs accepted on purpose.
Production risks and how they were controlled.
Small steps, visible changes, fewer surprises.
- 01
Audited the PHP monolith and mapped all 47 API endpoints, identifying 12 high-traffic hotspots causing 80% of the latency issues.
- 02
Implemented Strangler Fig pattern, routing traffic endpoint-by-endpoint from monolith to new Node.js/Go microservices behind an API Gateway.
- 03
Built Kafka-based event bus for order lifecycle events (placed → confirmed → dispatched → delivered), decoupling services from synchronous calls.
- 04
Deployed on ECS/EKS with Kubernetes auto-scaling tied to order queue depth, handling 3x traffic spikes during promotions without manual intervention.
- 05
Ran both systems in parallel for 6 weeks, comparing response times and error rates before fully cutting over.
What carries over to your system.
- Started by migrating the order search API first: low risk, high visibility. This built team confidence before touching the critical checkout flow.
- Kafka consumer lag monitoring was essential. Without it, we missed a 2-hour delay in order confirmations during the first week. Added CloudWatch alarms on consumer group lag.
- Blue-green deployments saved us twice during the migration. One bad Go service release was rolled back in under 30 seconds with zero customer impact.
Rollback path
The strangler path kept old and new services running in parallel so endpoint rollback stayed possible during migration.
Cost considerations
Cost reduction came from removing overprovisioned instances and scaling around real order traffic rather than peak fear.
Observability notes
P99 latency, order error rate, queue/consumer lag, deploy health, and checkout-path alarms mattered more than generic dashboard count.
Services built on this work
- AWS Production Architecture Review
- AWS Cost Optimization and FinOps Review
- Serverless and Event-Driven Platform Build
Have a similar production problem?
Send the current architecture, bill concern, deployment pain, or GenAI reliability issue. I will help you find the first real bottleneck.
 Request the reliability audit