LLM Infrastructure Training
Models wrote valid but unsafe IaC → 500+ reviewed CDK patterns, each paired with the security, cost and reliability reason behind it.
- Role
- LLM Infrastructure Trainer
- Context
- AI / Enterprise
- Duration
- 8 months
- Team
- Specialized trainer (me) + the program's AI team
Tech stack
- AWS CDK
- CloudFormation
- TypeScript
- Python
- AWS Bedrock
- Lambda
- VPC
- IAM
- Terraform
- RLHF


Business problem and production context.
Business problem
The program needed LLMs that could generate production-quality AWS CDK and CloudFormation code. Existing models produced syntactically correct but architecturally flawed infrastructure code, missing security best practices, cost optimization patterns, and Well-Architected Framework alignment.
Architecture decision
Created high-quality training datasets of AWS infrastructure patterns covering VPC design, IAM policies, Lambda configurations, and multi-account setups. Designed reusable TypeScript CDK constructs as reference implementations. Validated AI-generated infrastructure code against security, cost efficiency, and Well-Architected principles through systematic RLHF feedback loops.
Before and after.
Generated infrastructure code is judged on security, cost and design intent, and that reasoning goes back to the model as feedback.
The review and feedback loop the trainer role worked in. The program's model training and serving infrastructure is not shown.
Main components only; supporting services are left out.
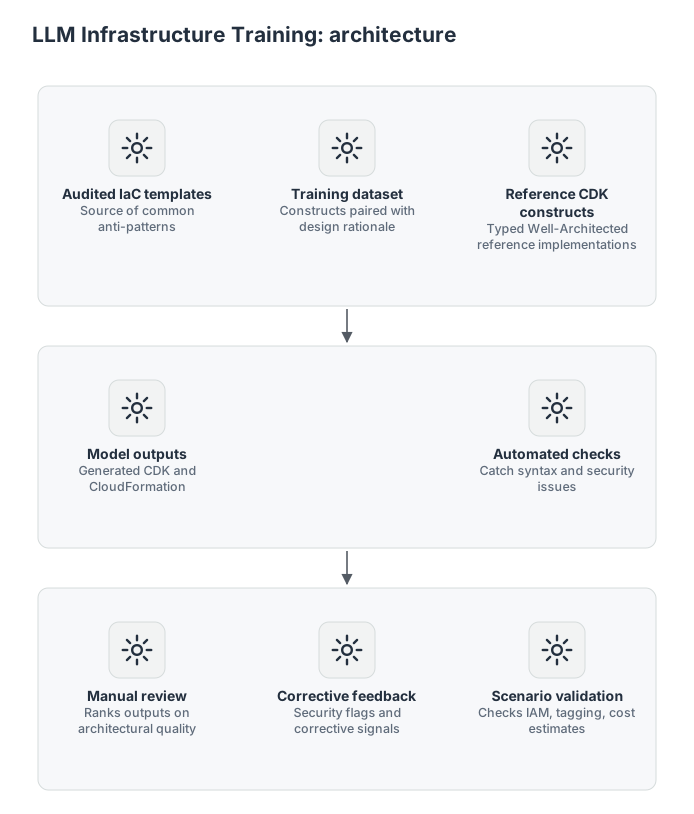
1. Reference data
Audited IaC templates
Source of common anti-patterns
Training dataset
Constructs paired with design rationale
Reference CDK constructs
Typed Well-Architected reference implementations
2. Model output
Model outputs
Generated CDK and CloudFormation
Automated checks
Catch syntax and security issues
3. Review and feedback
Manual review
Ranks outputs on architectural quality
Corrective feedback
Security flags and corrective signals
Scenario validation
Checks IAM, tagging, cost estimates
How it works, step by step
- 1Existing CDK and CloudFormation templates are audited for recurring gaps such as missing encryption and overly broad IAM roles.
- 2Correct constructs, each paired with its security, cost and reliability reasoning, go into the training dataset alongside typed TypeScript reference constructs.
- 3Model outputs pass automated syntax and security checks, then manual review for architectural quality and rationale.
- 4Each output is ranked by infrastructure quality, with security violations flagged and corrective signals returned to the program's AI team.
- 5Outputs from the trained model are validated against production deployment scenarios for IAM correctness, tagging and cost estimates.
Guardrails
- Every pattern carries its security, cost and reliability rationale
- Automated syntax and security checks before manual review
- Security violations flagged on every reviewed output
- Reference constructs follow the Well-Architected Framework
Considered and not used
- Python CDK for reference constructs: TypeScript gave stronger type safety and IDE support; models learn better from typed code.
- Coverage of every AWS service: Focused on the most common AWS patterns for higher quality on critical paths.
My part of the work, separate from the team's.
The team behind the engagement is in the facts row above. These are the parts I was responsible for, and the artifacts that show the work.
Owned scope
- Infrastructure review and training feedback for LLM-related IaC patterns
- AWS infrastructure judgment applied to model-training and evaluation workflows
- Quality feedback on infrastructure tasks where correctness, security, and maintainability mattered
Evidence artifacts
What would fail first?
Every project has constraints. The useful work is naming them early enough that rollback, cost, and ownership are designed before an incident.
Internal proof
Details are intentionally limited because the work is internal/NDA-sensitive.
IaC correctness
Training tasks needed secure and maintainable infrastructure patterns, not only syntactically valid snippets.
Evaluation quality
Feedback had to distinguish acceptable cloud patterns from risky production shortcuts.
Trade-offs accepted on purpose.
Production risks and how they were controlled.
Small steps, visible changes, fewer surprises.
- 01
Audited 500+ existing CDK/CloudFormation templates to identify common anti-patterns in AI-generated infrastructure code: security gaps, missing encryption, overly permissive IAM roles.
- 02
Created structured training datasets: correct CDK constructs paired with explanations of why each design decision was made (security, cost, reliability rationale).
- 03
Designed reusable TypeScript CDK constructs following AWS Well-Architected Framework. These became reference implementations for model training.
- 04
Ran the RLHF feedback loop: reviewed model outputs, ranked by infrastructure quality, flagged security violations, and provided corrective signals.
- 05
Validated trained model outputs against production deployment scenarios, measuring IAM policy correctness, resource tagging compliance, and cost estimation accuracy.
What carries over to your system.
- The biggest quality gap wasn't syntax; it was architectural intent. Models could write valid CDK but didn't understand WHY you'd choose a VPC endpoint over a NAT gateway. Training on rationale, not just code, was the breakthrough.
- Security-specific training data had the highest impact. A focused dataset of 50 IAM policy patterns improved security compliance more than 200 general infrastructure examples.
- RLHF feedback on cost implications was critical. Models needed to understand that a t3.micro vs m5.xlarge choice isn't just a parameter: it's a cost decision that repeats for every instance, every month.
Rollback path
Public details are constrained; the transferable lesson is to treat generated IaC as production-risky until reviewed.
Cost considerations
The public value is expertise signal rather than client savings disclosure.
Observability notes
The work reinforces why AI-generated infrastructure must be evaluated against operations, security, and maintenance.
Further reading
Services built on this work
Have a similar production problem?
Send the current architecture, bill concern, deployment pain, or GenAI reliability issue. I will help you find the first real bottleneck.
 Request the reliability audit