SaaS Platform Arch
ClickOps + slow environments blocking ship → serverless API with a 99.9% availability target, 40% AWS cut, envs in minutes.
- Role
- Lead Platform Engineer
- Context
- Developer Tools SaaS
- Duration
- 6 months
- Team
- 3 engineers + 1 architect (me)
Why they called
The platform had to go from pilot to production without adding operations headcount. Twenty-three resources had been provisioned by hand across three AWS accounts with no IaC, standing up an environment took three days, every deploy meant 15 to 30 minutes of downtime, and there was no monitoring to say whether anything was healthy.
Tech stack
- Python
- Lambda
- API Gateway
- DynamoDB
- Celery
- Terraform
- React
- Docker
- Kubernetes


Business problem and production context.
Business problem
The platform needed to scale from pilot to production-grade with minimal operational overhead. Build operations were slow, monitoring was non-existent, and infrastructure was manually provisioned, slowing feature delivery to a crawl.
Architecture decision
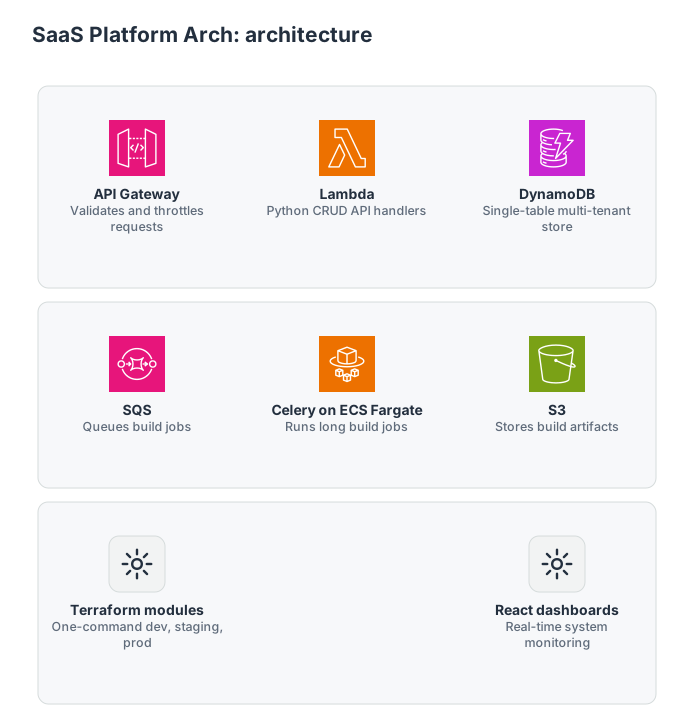
Designed a serverless API using Python, Lambda, API Gateway, and DynamoDB, with long build jobs on containers. Implemented Celery-based task queues with SQS for async build operations and deployment coordination. Built React/TypeScript dashboards for real-time system monitoring.
Before and after.
Lambda serves the multi-tenant API while long build jobs run on queued container workers, all stood up from one set of Terraform modules.
The API path, the async build pipeline and the provisioning layer. Authentication, networking, deploy tooling and the account layout are not shown.
Main components only; supporting services are left out.
API path

API Gateway
Validates and throttles requests

Lambda
Python CRUD API handlers

DynamoDB
Single-table multi-tenant store
Build pipeline

SQS
Queues build jobs

Celery on ECS Fargate
Runs long build jobs

S3
Stores build artifacts
Provisioning and visibility
Terraform modules
One-command dev, staging, prod
React dashboards
Real-time system monitoring
How it works, step by step
- 1API Gateway validates and throttles each request, then calls a Python Lambda handler.
- 2The handler reads and writes tenant data in one DynamoDB table, with GSIs for each multi-tenant access pattern.
- 3When a request starts a build, the handler puts a job on the SQS builds queue.
- 4Celery workers on ECS Fargate pull the job, run it under a hard timeout, and write artifacts to S3.
- 5Terraform modules stand up the same stack for dev, staging and prod with one command.
Guardrails
- Request validation and throttling at API Gateway
- Hard timeout on build jobs so a runaway build cannot run up compute cost
- Provisioned concurrency on the most-hit endpoints to avoid cold starts
- S3 lifecycle policies on build artifacts
- X-Ray active tracing on API handlers
- Blue-green deploys
Considered and not used
- Step Functions: Celery and SQS chosen for flexibility in complex build orchestration workflows.
- PostgreSQL: DynamoDB chosen for low latency and zero-ops scaling under unpredictable SaaS workloads.
- Lambda for build jobs: ECS chosen for long-running build jobs; Lambda kept for API handlers.
- A database per customer: Single-table design with GSIs serves every tenant from one table.
My part of the work, separate from the team's.
The team behind the engagement is in the facts row above. These are the parts I was responsible for, and the artifacts that show the work.
Owned scope
- Platform foundation for repeatable environments, IaC, deployment paths, and operational ownership
- Cost and reliability review for a SaaS product moving from pilot shape toward production scale
- Developer workflow improvements so environments could be created and changed predictably
Evidence artifacts
What would fail first?
Every project has constraints. The useful work is naming them early enough that rollback, cost, and ownership are designed before an incident.
ClickOps drift
Manual infrastructure changes made environments slow to create and hard to compare.
Small team
The platform had to reduce operational load instead of adding process overhead.
Growth pressure
Pilot decisions needed to become repeatable before more tenants and features arrived.
Trade-offs accepted on purpose.
Production risks and how they were controlled.
Small steps, visible changes, fewer surprises.
- 01
Mapped the existing manual infrastructure and documented 23 hand-provisioned resources across 3 AWS accounts with no IaC.
- 02
Designed API-first architecture. Lambda handlers for all CRUD operations behind API Gateway with request validation and throttling.
- 03
Built async build pipeline using Celery workers on ECS, SQS for job queuing, and S3 for artifact storage with lifecycle policies.
- 04
Implemented DynamoDB single-table design with GSIs for multi-tenant access patterns, eliminating the need for a separate database per customer.
- 05
Created Terraform modules for the full stack, enabling one-command environment provisioning for dev/staging/prod.
What carries over to your system.
- DynamoDB single-table design requires upfront investment in access pattern analysis. We spent 2 weeks modeling before writing code, but saved months of schema migrations later.
- Lambda cold starts were noticeable for the first user request after idle periods. Solved with provisioned concurrency on the 3 most-hit endpoints. A small monthly cost, well worth the UX improvement.
- Celery on ECS Fargate worked well but needed careful task timeout configuration. A runaway build job can rack up compute cost fast, so we added a 15-minute hard timeout.
Rollback path
Rollback needed to be tied to deployment workflow, state changes, and environment promotion instead of manual memory.
Cost considerations
The primary savings path was right-sizing and removing manually-created resources that had no owner.
Observability notes
Environment health, deploy success, core API latency, and tenant-impact signals were the important baseline.
Further reading
Services built on this work
- AWS Production Architecture Review
- AWS Cost Optimization and FinOps Review
- Serverless and Event-Driven Platform Build
Have a similar production problem?
Send the current architecture, bill concern, deployment pain, or GenAI reliability issue. I will help you find the first real bottleneck.
 Request the reliability audit