Security Automation
Monthly PDF scans + post-breach discovery → continuous scanning, <5s detection, CI gates devs actually use.
- Role
- SDE-II
- Context
- Cybersecurity / SaaS
- Duration
- 7 months
- Team
- 5 engineers + 1 SDE-II (me)
Tech stack
- Python
- FastAPI
- React
- TypeScript
- PostgreSQL
- Redis
- AWS Lambda
- SNS
- SQS
- Docker
- GitHub Actions


Business problem and production context.
Business problem
Security teams lacked visibility into API-layer threats. Manual security reviews took weeks, vulnerability backlogs grew faster than they could be triaged, and there was no runtime protection. Threats were only caught post-breach in log analysis.
Architecture decision
Developed Python backend services for automated API security scanning and threat detection. Built a React security dashboard with real-time threat visualization, risk scoring, and compliance status tracking. Implemented event-driven alerting with SNS/SQS for instant notification on critical vulnerabilities. Improved CI/CD pipeline efficiency by 25% with automated security gates.
Before and after.
Continuous API scanning that classifies each finding and routes alerts by each organization's preferences.
The scan, detection and alerting path. Networking, model training and the hosting of the scan service and dashboard are not shown.
Main components only; supporting services are left out.
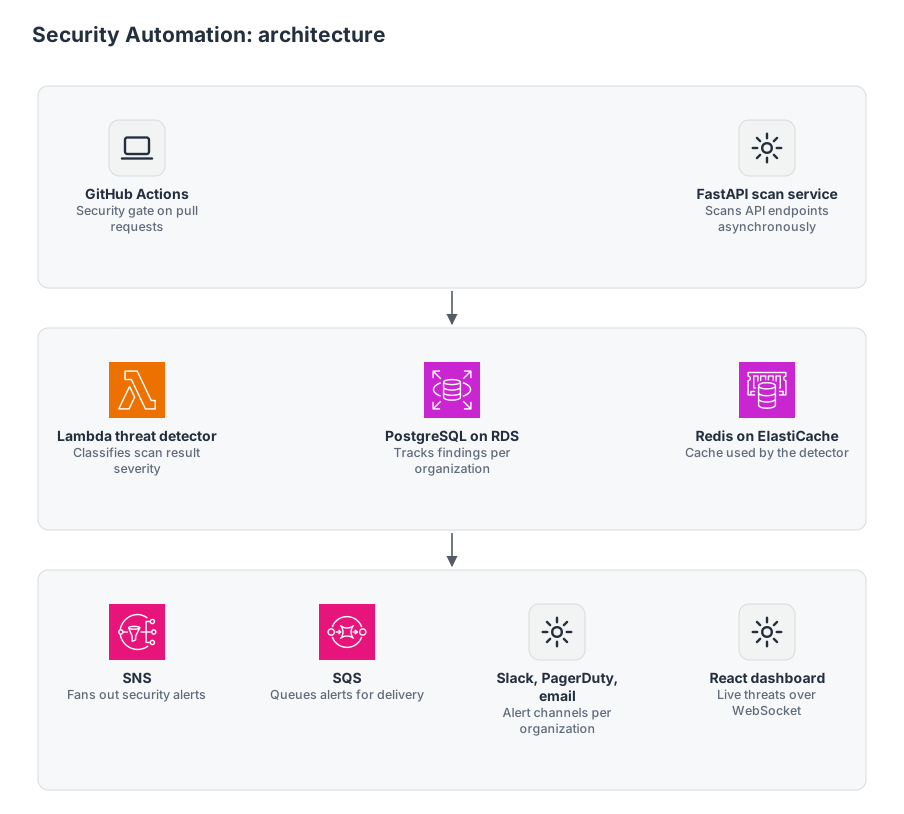
1. Scan entry
GitHub Actions
Security gate on pull requests
FastAPI scan service
Scans API endpoints asynchronously
2. Detection and findings

Lambda threat detector
Classifies scan result severity

PostgreSQL on RDS
Tracks findings per organization

Redis on ElastiCache
Cache used by the detector
3. Alerting and visibility

SNS
Fans out security alerts

SQS
Queues alerts for delivery
Slack, PagerDuty, email
Alert channels per organization
React dashboard
Live threats over WebSocket
How it works, step by step
- 1A scan starts from the continuous scanner or from the security gate on a pull request, and the FastAPI service scans the API endpoints asynchronously.
- 2The Lambda threat detector processes each scan result and classifies its severity with a custom ML model.
- 3Findings are stored in PostgreSQL as assets, scans, findings and remediation status, separated by organization.
- 4SNS and SQS fan critical alerts out to Slack, PagerDuty or email based on each organization's preferences.
- 5The React dashboard pushes active threats, risk score trends and OWASP compliance status to SOC teams as they happen.
Guardrails
- Row-level security keeps each organization's findings separate
- Every pull request passes a security gate whose threshold is set per repo
- The detector Lambda runs in private subnets behind its own security group
- Real-time scans cover critical paths, and weekly batch audits cover the rest
Considered and not used
- EventBridge: SNS and SQS gave a simpler fan-out for routing alerts across channels.
- DynamoDB: PostgreSQL handles security queries that join vulnerability, asset and compliance tables.
- Django: FastAPI was chosen for async request handling under high concurrency.
My part of the work, separate from the team's.
The team behind the engagement is in the facts row above. These are the parts I was responsible for, and the artifacts that show the work.
Owned scope
- The FastAPI scanning backend: async request handling so API endpoints are scanned continuously instead of monthly
- The PostgreSQL schema for multi-tenant findings (assets, scans, findings, remediation status) with row-level security per organization
- Severity classification on scan results and SNS/SQS alert routing to Slack, PagerDuty or email by each organization's preferences
- The real-time React dashboard over WebSocket, and CI/CD security gates with thresholds set per repository
Evidence artifacts
What would fail first?
Every project has constraints. The useful work is naming them early enough that rollback, cost, and ownership are designed before an incident.
Signal quality
The first severity classifier raised too many false positives and engineers ignored the alerts; retraining it on customer feedback is what made alerts worth reading.
Tenant isolation
One organization's findings must never reach another, so isolation lives in the database as row-level security, not only in application code.
Developer adoption
A gate that is too strict gets bypassed and one that is too lenient lets critical findings ship, so thresholds are set per repository.
Trade-offs accepted on purpose.
Production risks and how they were controlled.
Small steps, visible changes, fewer surprises.
- 01
Analyzed existing security workflow: manual Burp Suite scans triggered monthly, results emailed as PDFs, no centralized tracking or prioritization.
- 02
Built FastAPI backend with async request handling for real-time API endpoint scanning. Each scan runs in under 5 seconds for standard REST APIs.
- 03
Designed PostgreSQL schema for multi-tenant vulnerability tracking: assets → scans → findings → remediation status, with row-level security per organization.
- 04
Implemented event-driven alerting pipeline: Lambda processes scan results, classifies severity via custom ML model, fans out via SNS to Slack/PagerDuty/email based on org preferences.
- 05
Created React dashboard with real-time WebSocket updates showing active threats, risk score trends, and compliance status against OWASP Top 10.
What carries over to your system.
- False positive rate was the biggest adoption blocker. Initial ML classifier had 30% false positive rate. Engineers ignored alerts. After retraining with customer feedback data, got it down to 4%.
- Real-time WebSocket dashboard was the feature that sold the product to SOC teams. Static dashboards weren't enough. They needed to see threats appearing live during active incidents.
- Integrating security gates into CI/CD required careful threshold tuning per team. Too strict and developers bypass it, too lenient and critical vulns ship. Made thresholds configurable per repo.
Rollback path
A gate that blocks too much is relaxed for one repository through its threshold, without switching it off for every team.
Cost considerations
Cost follows scan volume: continuous scans on critical paths, weekly batch audits for the rest.
Observability notes
The useful view was active threats, risk score trends and OWASP Top 10 status, updated live for SOC teams during incidents.
Further reading
Services built on this work
Have a similar production problem?
Send the current architecture, bill concern, deployment pain, or GenAI reliability issue. I will help you find the first real bottleneck.
 Request the reliability audit